Document ingestion
Connectors for PDFs, knowledge bases, tickets, and databases, kept in sync.
AI & Agent Engineering
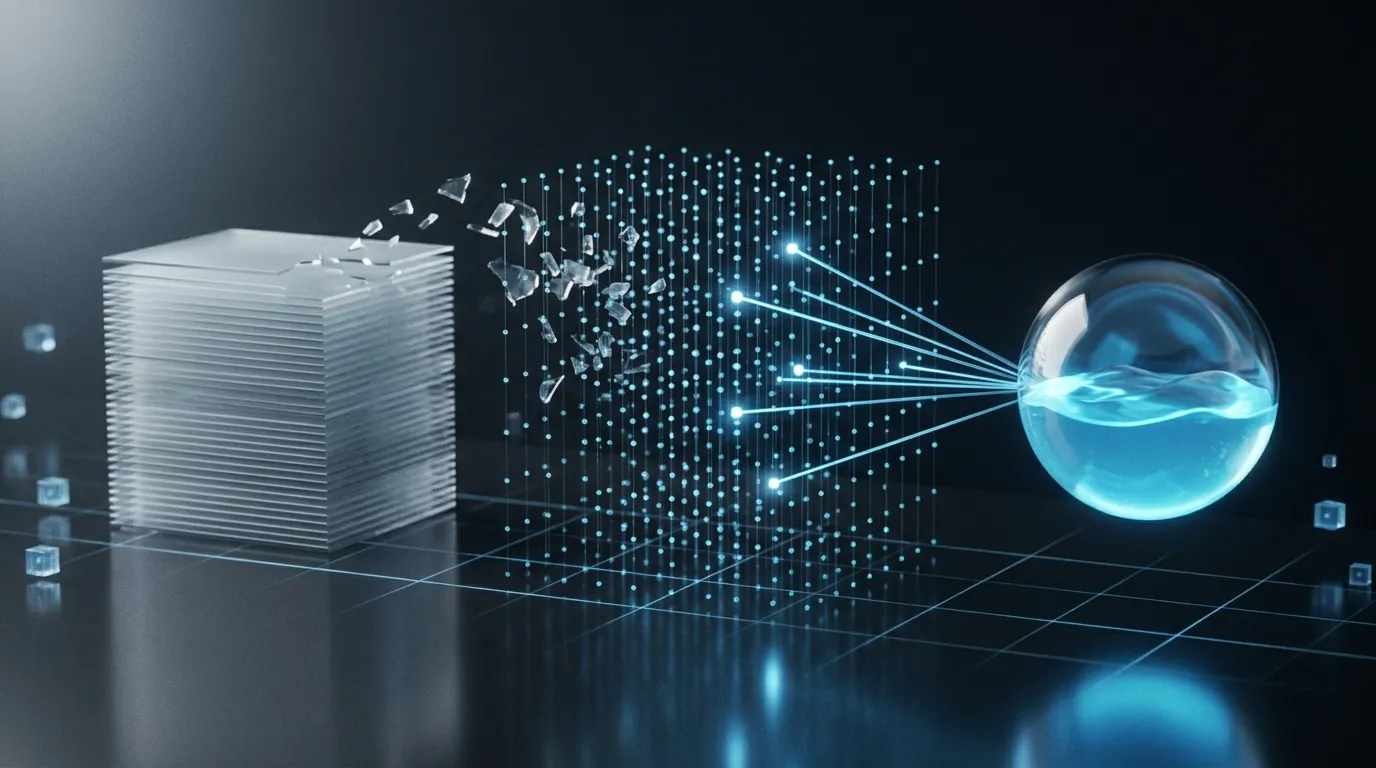
Retrieval-augmented generation (RAG) lets a language model answer from your own documents and data instead of guessing from its training.
We build the whole pipeline — ingestion, chunking, embeddings, vector search, re-ranking, generation, and evaluation — so answers are accurate, cited, and secure.
CAPABILITIES
Connectors for PDFs, knowledge bases, tickets, and databases, kept in sync.
Chunking strategies and embedding models matched to your content.
Pinecone, PgVector, or Chroma — picked for your scale, latency, and hosting needs.
Hybrid search and re-ranking so the right passages reach the model.
Answers with citations, confidence states, and safe fallbacks.
Per-tenant isolation, access-aware retrieval, and private deployments.
TOOLS
Chosen per use case, not by default.
 OpenAI
 Claude AI
 Gemini
 Llama
 Gemma
 LangChain
 LangGraph
 CrewAI
 AutoGen
 Hugging Face
 Pinecone
 PgVector
 Chroma
 Whisper
 Stable Diffusion
 PyTorch
 TensorFlow
OUR APPROACH
Seven steps, one team. Intelligence is scoped at the start and evaluated at the end.
We start every engagement by mapping where intelligence belongs in your product: which workflows an agent can own, where an LLM adds real value, and where plain software is the right answer. You get an honest AI scope — including what not to build.
Research, flows, wireframes, and high-fidelity interfaces, validated with users before development begins. For AI features, we design the states that matter: streaming, uncertainty, and human-in-the-loop control.
Model selection, prompt and agent architecture, RAG pipeline design, and evaluation harnesses — built with LangChain, LangGraph, CrewAI, and the vector store that fits your data.
Frontend and backend engineering on React, Next.js, Node, and Python, delivered in short sprints with working software at the end of each one.
Native and cross-platform apps for iOS and Android, built against the same APIs and design system as the web product.
Infrastructure as code, CI/CD, and monitored releases on AWS, Azure, or GCP — including GPU/inference infrastructure and model-cost monitoring where AI workloads demand it.
Automated test suites cover every release. AI features get their own evaluation suites — regression tests for prompts, hallucination checks, and output-quality scoring — so intelligence ships with the same rigor as code.
FAQ
Retrieval-augmented generation retrieves relevant passages from your own data and gives them to a language model, so the answer is grounded in your content and can cite its source.
Use RAG when answers depend on knowledge that changes or must be cited. Use fine-tuning to change style, format, or a narrow skill. Most products start with RAG and add fine-tuning only if evaluation shows a gap.
PgVector suits teams already on PostgreSQL, Pinecone suits large managed workloads, and Chroma suits prototypes and self-hosting. We choose based on scale, latency, and where your data must live.
With a test set of real questions scored for retrieval accuracy, answer faithfulness, and citation correctness, run on every change.
Tell us what you're building — we'll show you where AI belongs in it.